Advancements in Viral Protein Research
A significant upgrade is underway for a comprehensive database that predicts the structures of nearly all known proteins on Earth, with a focus on some of the most obscure yet lethal organisms: viruses.
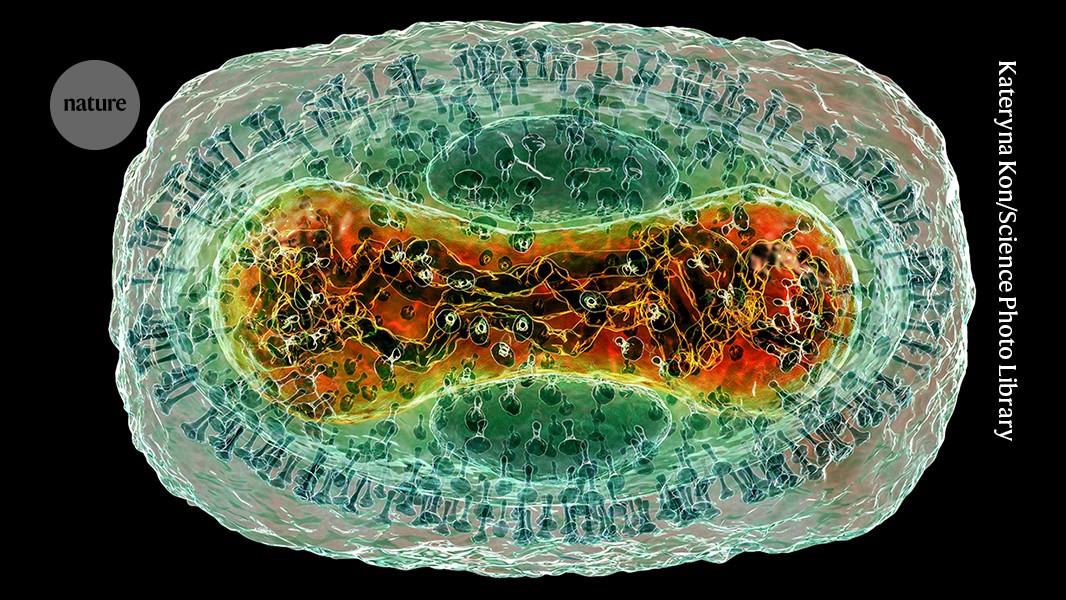
Researchers have recently included over 8,000 virus protein dimers—these are pairs of interacting proteins—into the AlphaFold Protein Structure Database. This impressive collection is aided by the AlphaFold2 AI tool, which generates three-dimensional protein structure predictions that are accessible to everyone. These new additions stem from 23 families of viruses, all of which have the potential to infect humans, and they launch a ‘pandemic preparedness portal’ within the widely utilized AlphaFold database.
Earlier this year, there was a significant contribution of predicted structures for 1.7 million interacting protein pairs from 20 extensively studied organisms, including humans and common pathogens like those causing tuberculosis. This marked a milestone, as it was the first time protein complexes, such as enzymes formed by two identical protein strands, were represented in the AlphaFold database. This resource is managed by the European Molecular Biology Laboratory’s European Bioinformatics Institute (EMBL-EBI) in Hinxton, UK.
“Many viral proteins do not act alone; they work alongside their partners,” Joe Grove, a molecular virologist at the University of Glasgow, UK, noted, mentioning his involvement in adding these viral protein complexes.
A Notable Gap
Although the database boasts more than three million users and covers a majority of recognized proteins, it still has a significant gap when it comes to viruses, Grove points out. There’s a notable absence of high-quality entries for various individual proteins linked to flaviviruses, which include well-known types like Zika and dengue.
This shortfall relates to the replication process of some viruses, where their RNA is converted into what’s termed a ‘polyprotein’, which is subsequently divided into distinct functional proteins. Consequently, discerning where one protein ends and another begins based on the genetic sequence can be quite challenging, often resulting in incomplete predictions of their structures.
To enhance the accuracy of these entries, researchers from the Swiss Institute of Bioinformatics in Geneva have identified precise sequences for thousands of viral proteins derived from polyproteins. Grove and his team, in collaboration with various global institutions, examined the sequences of 41,774 proteins from roughly 2,800 viruses, including those responsible for mpox, measles, and hepatitis B.
Using these sequences, they employed AlphaFold2 to predict structures for 40,746 homodimers—pairs of identical interacting proteins—and nearly 1.7 million heterodimers, which are unique pairs. However, only 2,749 of the homodimers and 5,279 of the heterodimers were sufficiently accurate for inclusion in the AlphaFold database, even though all predictions are available for public access.
It’s important to note that many viral proteins feature sugar molecules that help them evade detection by the immune system. Additionally, some viral functions occur in larger complexes rather than just dimers. For instance, the spike protein of SARS-CoV-2 consists of three identical proteins, similar to the envelope-entry protein of HIV. This means that many dimer predictions won’t make it to the AlphaFold database, particularly if they fall short of accuracy, as Grove points out.
Sameer Velankar, a bioinformatician at EMBL-EBI involved in the project, believes that including predictions for larger complexes, or ‘trimers’, should be a priority. However, when it comes to larger assemblies, determining how many components are in each complex can get quite complicated.
Grove is enthusiastic about diving into this new data to advance his research on how viral proteins facilitate entry into host cells. “Ultimately, the proof will be in the pudding,” he remarked, alluding to the importance of making this data available for research teams like his to further explore.